Updating a Hiring Standard Mid-Search Without Breaking the Pipeline
Changing hiring standards mid-search requires documenting the shift, not restarting from scratch.
Hiring standards are not fixed targets. They shift mid-search, predictably, and the pipeline built against the old standard is a living system of real candidates, relationships, and sourcing work that a restart simply throws away. The real question is how to change standards without breaking what the search has already built.
Why hiring standards change mid-search
Three events trigger a mid-search standard change, and all three are predictable enough to plan around. A team sees its first real candidates and realizes the original spec was written from guesswork, not market evidence. A competing priority shifts what the role actually needs to do. Or a single standout candidate at a different level resets what "exceptional" means to that panel. None of these are edge cases. Every search long enough to generate real signal will hit at least one.
That makes this a design problem. The panel didn't do something wrong by learning more about the role halfway through. What happens next matters, because the default answer, restarting the search, is usually the most expensive option on the table.
A restart doesn't reset the clock to zero. It costs more than zero, because every day spent reopening sourcing is a day the role stays unfilled, and unfilled roles cost businesses an average of $500 a day in lost productivity according to HackerEarth's candidate pipeline analysis. Employ's 2026 Hiring Benchmarks Report also points to a quieter cost: when criteria shift midway through a process and feedback loops stay inconsistent, interviews stop converting, a pattern especially visible among mid-market and small businesses. That conversion drop is the clearest sign available that a pipeline's health is deteriorating.
There's a second failure mode that looks less dramatic than a restart but does comparable damage: quietly moving the bar without telling anyone, including the candidates affected by it. Candidates get cut without ever knowing the standard changed. Others get passed through without clearing a bar anyone could actually describe out loud. The pipeline looks like it's moving. It's actually leaking. What drives the rest of this piece is that the change stayed invisible, undocumented, and was never applied back to the candidates already in motion.
What "bar drift" looks like in a live pipeline
Bar drift is the most common version of a mid-search standard change, and it happens without anyone deciding to change anything. Under pressure to fill a role, hiring managers unconsciously lower the bar. Interviewers who haven't seen a genuinely exceptional candidate in weeks reset their internal sense of what "strong" looks like, downward, without flagging that anything has shifted. The reverse happens too. One standout candidate, operating a level above what the job description described, resets the panel's reference point upward, and candidates interviewed earlier get silently re-measured against a bar that didn't exist when they walked in the door.
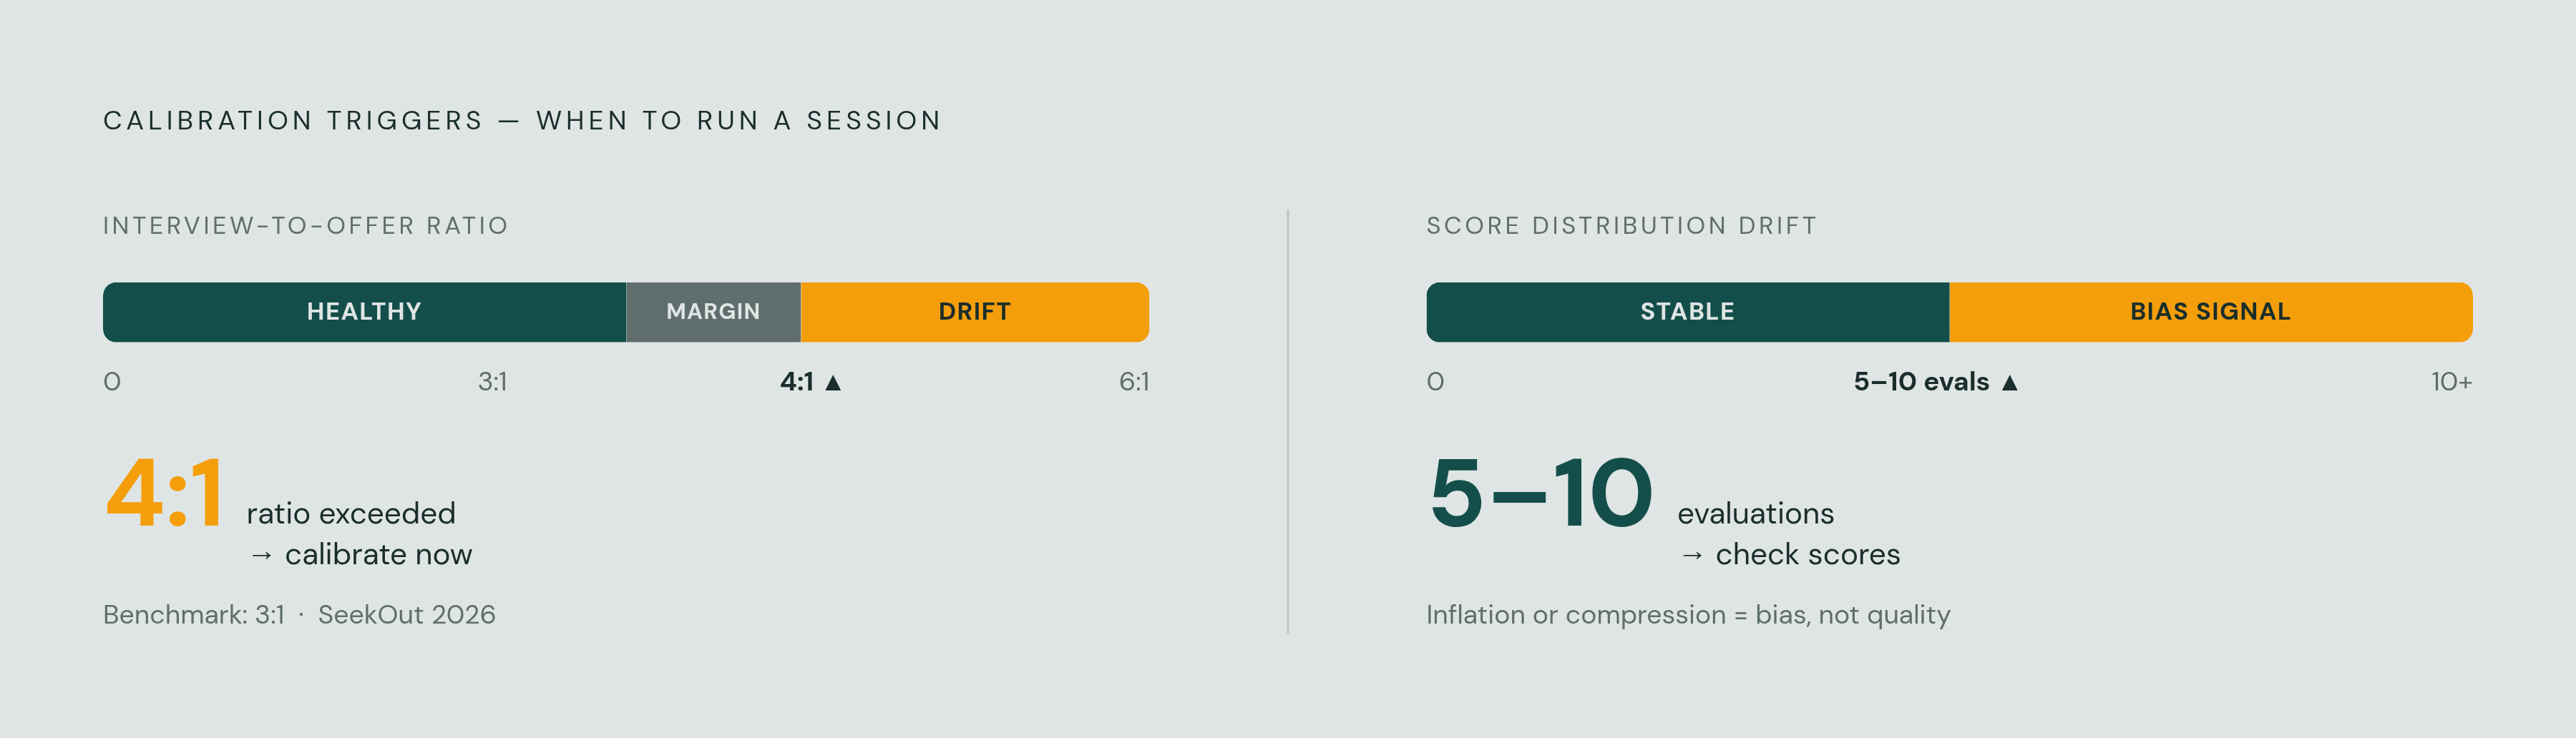
Score patterns give this away before anyone notices it in conversation. Run enough evaluations through the same role family, and scores start to inflate ("everyone's a strong yes") or compress ("everyone's a 3"). Neither pattern says anything about the actual candidates. Both say the panel recalibrated without ever naming that it did. These are bias signals, not quality signals, and they stay invisible unless someone actually pulls the scoring distribution and looks at it over time.
Executive and senior hiring is especially exposed to this because the process front-loads confidence and leaves calibration for later. A strong resume, a polished LinkedIn profile, a well-written job description all combine to make a candidate feel inevitable before anyone has done the actual work of testing that impression against evidence of what the person has built. Calibration tests assumptions against evidence at every stage of the process, not just at the final debrief.
Small organizations feel this most acutely because they're the least likely to have formal calibration built into the process. Employ's 2026 benchmarks put small-company interview-to-offer conversion at 7.0%, the lowest and most volatile figure in the dataset. That number lines up with undocumented bar drift more than it lines up with weak sourcing. The pipeline isn't failing because the sourcing is bad; it's failing because the standard keeps moving without anyone writing down where it moved to.
Why the original standard was probably built on assumptions rather than market evidence
A mid-search recalibration is a correction of an error built into the job description before the search ever started. Most hiring standards get written before the team has seen a single real candidate for that role. They're built on assumptions the market hasn't tested yet. The search itself is the test. Finding out the original bar was wrong partway through is the process doing exactly what it's supposed to do, a few weeks later than anyone would prefer.
Job descriptions tend to lean on familiar credentials, degree requirements, years of experience, brand-name employers, as stand-ins for the thing that actually predicts performance: evidence of what someone has built, at what scope, under what real constraints. A degree, an MBA, a decade of tenure are inputs. They are not outputs. The question that actually predicts whether someone succeeds in the role is whether their track record, their scope of responsibility, and the conditions they operated under match what this specific job demands.
The market is already moving in this direction. Manatal's Recruitment Trends Report documents degree requirements being stripped out at scale, as employers discover that formal education does not always reflect current, deployable skills. Employers are now hiring for what candidates can do today rather than what they studied. Organizations that have already dropped degree requirements for specific roles report hiring strong candidates who would have been screened out under the old standard, proof that the original bar was filtering for credential rather than capability.
One might argue that any mid-search change risks looking arbitrary to candidates and hiring managers alike. That's fair, and it's exactly why the distinction matters between a standard update driven by real market evidence, "we've now seen what this candidate pool actually looks like," and one driven by impatience or a single loud opinion in a debrief. The first is the market correcting a flawed starting assumption. The second is a moving goalpost. Telling them apart is the judgment call the rest of this framework exists to support.
How a calibration session differs from an interview debrief
An interview debrief and a panel calibration session do two different jobs, and treating them as interchangeable is how a standard update turns into chaos. A debrief is backward-looking and candidate-specific: the panel reviews one person against a shared rubric and decides hire or no-hire. Calibration is forward-looking and rubric-specific: it's the work of getting interviewers to score the same signals the same way, before the debrief ever starts.
Skip calibration, and the debrief absorbs work it was never built to do. It stretches into a prolonged argument, and whoever argues loudest ends up setting the new standard by default, without anyone ever writing it down as a standard change. Done well, calibration actually shortens the debrief, because the panel walks in already aligned on what they're looking for.
The research on panel size backs this up in a specific way: more interviewers isn't the fix, shared standards are. Laszlo Bock, former SVP of People Operations at Google, published the company's internal hiring data in Work Rules!, showing that four interviewers were enough to predict a new hire's performance with strong reliability. Adding a fifth, sixth, or seventh interviewer raised accuracy by only a negligible margin each time. The lesson is to make sure the interviews that happen are evaluating against the same explicit bar, rather than four different implicit ones.
This is the part of the process that should absorb a standard change. A calibration session is where "what we're looking for" gets renegotiated out loud, written down, and applied evenly. A debrief that quietly turns into a standard-setting conversation leaves no record of what changed or why, and that absence of a record is what produces bar drift.
A framework for making a mid-search standard change explicit, documented, and retroactively applied
Three things need to happen for a mid-search standard change to avoid wrecking the pipeline: the change has to be made explicit, the reasoning behind it has to be written down, and every candidate already in the pipeline has to be re-evaluated against the new standard rather than quietly dropped or quietly waved through.
Making the change explicit means calling a calibration session specifically for this purpose, not folding it into a debrief. The session should name what changed, why it changed, and what the new bar looks like described in terms of actual behavior and evidence, not vague impressions. The trigger is one of the three events already named: a first real look at the market, a scope change, or a candidate who reset the panel's sense of what's possible. The output of that session should be a written rubric update, stated in terms of evidence of work rather than credentials.
Documenting the rationale is what separates a legitimate market correction from an arbitrary goalpost move. Every change to a hiring bar should be visible and reasoned, approved by a person, not something that only becomes apparent to candidates after the fact when they start getting mixed signals about where they stand.
Retroactive re-evaluation is the step most searches skip, and it's the one that matters most. Every candidate already active in the pipeline needs to run through the new rubric before anyone makes another decision. Applying the new bar only to new candidates, while judging earlier candidates against the old one, splits the pipeline into two groups being measured on different terms. That's not just unfair to candidates who showed up early. It also makes the data from the search useless for diagnosing anything, because nobody was being compared on equal footing.
Some platforms build this directly into the process. Journeyfront's re-ranking feature lets a team change scoring criteria at any point and re-rank every candidate in the pipeline instantly, without restarting the review from scratch. That's a concrete version of the retroactive-application principle: the standard moves, and the people already in motion move with it, rather than getting left behind under a rule nobody's applying anymore.
Two metrics tell a team when this process needs to run. SeekOut's 2026 recruiting metrics guide puts a healthy interview-to-offer ratio at 3:1, and flags anything above 4:1 as a sign too many borderline candidates are reaching final rounds. That ratio deteriorating mid-search is the signal to call a calibration session, not to start the search over. The second is simple volume: after five to ten evaluations within the same role family, scores start to show the inflation or compression patterns described earlier, and catching that early keeps the pipeline from distorting further. A quarterly calibration session, re-anchored against the team's own historical hiring data rather than generic industry numbers, keeps that drift from compounding. Journeyfront's approach of connecting assessment scores to actual post-hire retention and performance data gives teams a way to check whether their criteria predict success at all, and adjust with evidence instead of instinct.
None of this works without people making the actual call. A tool can surface the signal, flag a conversion ratio slipping past 4:1, or show a scoring distribution starting to compress. The decision to change the standard, document why, and apply it backward still belongs to the humans running the search.
How much sourcing and relationship capital a structured update preserves
The capital sitting inside an active search, sourced candidates, engaged prospects, strong runners-up from earlier rounds, doesn't survive a restart. CS Recruiters' 2026 talent pipeline guide found that organizations with mature, pre-qualified candidate pools cut average time-to-fill from 44 days down to under 21. A restart doesn't just slow things down. It forfeits that advantage completely and resets the clock to day one.
Silver medalists, the candidates who came in second in a previous search, are often the highest-return segment of any pipeline, precisely because they're already evaluated, already engaged, and already know the team. A structured rubric update can bring them back into consideration. A restart tends to lose them for good.
There's also a layer of engagement data that gets thrown away in a restart and rarely gets mentioned: who opened an outreach email, who showed up to an event, whose career timing suggests they're ready to move. A 30-day warming buffer before a role is even announced publicly is part of what builds that signal, and restarting a search burns through that buffer, forcing every relationship back to a cold start.
The staffing math behind all this makes the stakes sharper in 2026. Recruiter capacity is under real strain right now. Lina Kalysh's 2026 hiring strategy analysis, drawing on the 2026 Recruiting Benchmarks Report, shows hires per recruiter at a historic low while open roles per recruiter have climbed sharply. Recruiters simply have less room to rebuild what a restart tears down. In that environment, the choice is between rebuilding a pipeline from nothing or carrying forward the work already done, measured fairly, against the standard the team actually believes in now.