Every Calibration Change to Your AI Hiring Bar Needs an Owner a Reason and a Timestamp
Undocumented calibration shifts can exclude qualified candidates without a trace.
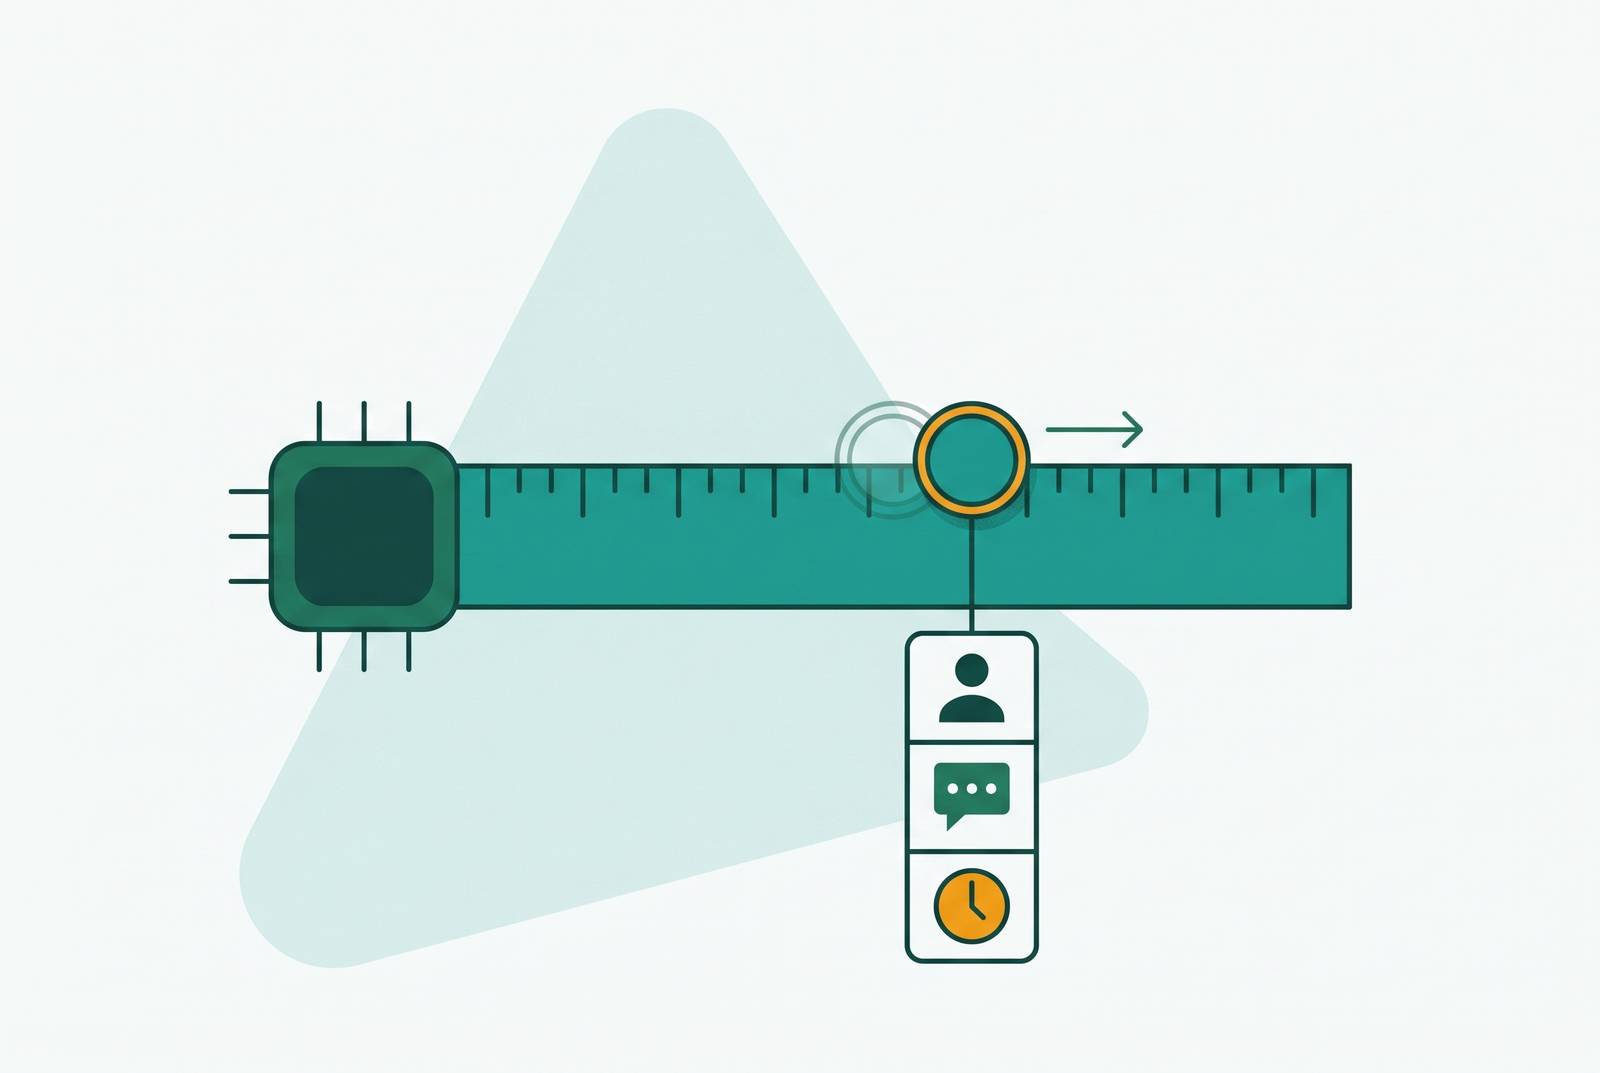
An AI recruiting tool with human-approved hiring standards needs its scoring criteria approved before it evaluates candidates, along with an audit trail that links each evaluation to the standard used. Every calibration change needs a named owner, a documented reason, and a timestamp. That is how a team can explain why candidates were ranked as they were, challenge the standard, and reverse a change that produces the wrong results.
Why an AI hiring bar is not a fixed setting but a decision surface that moves
Founders and talent acquisition leaders often think of calibration as an initial setup step. The team sets out what the role needs, agrees on the screen, and starts hiring. But that standard does not stay still. Labor markets shift, role requirements evolve, and feedback from earlier hiring rounds reshapes what the system surfaces next. A setting that once met the team's needs can stop fitting them while the workflow seems to run as usual.
The hiring bar is better understood as a decision surface. Thresholds determine who advances, scoring weights determine which evidence counts most, and screen-in criteria determine who qualifies for consideration. Each can move independently of the others. A bar can become tighter, looser, or just different, so it favors another kind of experience while the same number of candidates pass. Governing those movements requires checking that they are sanctioned and recorded, even while the software still works.
Agentic AI extends the reach of those choices. When a system connects sourcing, screening, outreach, and scheduling autonomously, a changed standard can shape several steps before a person sees a candidate. Human review comes later in the chain. By then, the system may already have decided whose experience deserves attention and whose does not. Calibration is still a choice about whom to hire even when it looks like a setting in the background.
What a shifted bar actually changes for candidates — and why the consequences are invisible by default
When that decision surface moves, candidates land on different sides of it. An undocumented adjustment does not merely alter a score. It changes who reaches a human reviewer, while those excluded have no way to see that the standard changed. A false positive may be visible in the inability of a candidate who advances to do the work. A false negative is harder to detect because the qualified person disappears from the funnel.
Kevin T. Webster's audit study found that some AI screening models appeared demographically balanced because they failed to distinguish candidates meaningfully. The study calls this the “Illusion of Neutrality.” Stable-looking outputs can therefore conceal a weak screen. The same study found context-dependent and intersectional bias, including models that penalized demographic signals and models whose patterns differed across roles and identities under controlled conditions. Neither apparent balance nor a steady flow of recommendations establishes that the bar is selecting well.
Strong builders without familiar credential markers are especially exposed when calibration drifts toward pattern-matching. People with the same experience do not always use the same words. Differences in how candidates describe their work correlate with educational background, native language, and socioeconomic status, so a screen that increasingly rewards keywords can mistake phrasing for capability. What would a downstream reviewer notice? Usually, only the candidates who survived that screen.
More volume can deepen that blind spot. Candidates who receive AI-generated outreach reply with AI-generated applications, and hiring teams tighten AI screening to keep up with the flood. A miscalibrated bar then operates faster and more widely. Human involvement at the end does not, by itself, examine the exclusions made earlier. The result can be a busy funnel that gives the team little reason to ask which capable people never entered the conversation.
Why undocumented calibration changes create an accountability vacuum no one on the team can fill
Who would know to investigate those missing candidates? When no owner is named, the employer, the vendor, and the recruiting team each bear part of the responsibility. Each may understand part of the process while no one can explain the whole decision. Recruiters may also respond differently to the same tool, with some relying heavily on its suggestions and others barely using them.
The standard can also change outside the employer's configuration work. Vendors may change models without notice, and training data can drift, so a tool that performed acceptably at launch can produce different outcomes months later. The employer need not have touched a setting. Without a change log, the team cannot establish when the shift happened or connect it to the decisions made around that time. Without a record, an investigation then starts with competing recollections.
A candidate's question makes the gap concrete. If someone asks why they were screened out, can the team identify the criterion applied, the person who approved it, and the date it took effect? Naming the recruiter who delivered the rejection is not the same as identifying who owned the standard. Pointing to the vendor also leaves unexplained why that standard was right for the role. The missing record prevents the team from separating an intended hiring choice from an unapproved shift.
That internal ambiguity now has an external counterpart. Mobley v. Workday has allowed claims to proceed under an “agent” theory, making vendor liability a live legal question without a final finding of liability. Both the employer and the AI vendor may face accountability for discriminatory outcomes. The practical gap therefore cannot be resolved simply by assigning the software to one party and the hiring decision to another.
What regulators and courts now require you to be able to prove about every automated hiring decision
New York City Local Law 144 requires employers who use automated employment decision tools to have independent bias audits done each year and make the results public. It also requires notice to New York City–resident candidates at least 10 business days before an AEDT evaluates them. An employer needs records that demonstrate the required steps occurred, rather than a general statement that its screening process is fair.
Other jurisdictions have distinct rules and dates. California's civil rights rules on automated decision systems have been in place since October 1, 2025, and the rules in Illinois and Texas took effect January 2026. Colorado replaced its original AI Act with SB 26-189, which takes effect January 1, 2027. The EU AI Act classifies AI hiring tools as high-risk, with the application date for those obligations delayed from August 2, 2026 to December 2, 2027 through the EU Digital Omnibus, Regulation 2026/1744. Fines remain up to €15M or 3% of global annual turnover.
Those regimes are not interchangeable legal checklists. Their shared practical demand is a stronger evidentiary record of how automated hiring works, particularly where recommendations influence final decisions. Those records include AI evaluations, the criteria that were used, when those criteria changed, and the results they led to. Under California's amended Fair Employment and Housing Act, how well records are kept can itself be evidence in a discrimination claim. A team unable to reconstruct its standard has a gap that a claim about fairness cannot fill.
A vendor able to provide a bias audit report, a model card, and a change log offers evidence that a promise of fairness does not. The employer still has its own responsibilities. Vendor documentation does not explain an employer's undocumented threshold change, just as an internal approval does not replace a required independent audit. The records need to connect the tool's behavior with the hiring choices made by the team using it.
How do you document human approval, reasons, and timestamps for every calibration change?
Record a named approver for each change before the revised standard evaluates candidates. At an early-stage company, that person may be the founder or the first TA hire. The role need not sit in legal or compliance. What counts is that a specific person accepts responsibility for the change and appears in its record.
A larger team can divide the work without dissolving that responsibility. In a practical governance RACI, recruiting ops is responsible for model configuration and scoring rules, people analytics is accountable, DEI and legal are consulted, and recruiters are informed. The division needs to remain legible. The person changing a weight and the person approving it may have different jobs, but neither should have to guess who owns the decision. Recruiters also need to know that the standard they are using has changed.
Write the reason in terms the team can challenge. Market evidence might show that the talent pool for a role at the company's stage does not contain enough candidates with a particular credential, supporting its removal as a screen-in criterion. Performance evidence might show that the last three hires who passed a screen underperformed within ninety days, prompting a proposal to tighten the threshold. Writing down the reason lets the team see thin evidence before it becomes a rule used across the funnel.
Attach the timestamp to the model version and the decision points affected by the change. To explain a candidate's ranking, keep the evaluation and the criteria used as well as the latest version of the hiring standard. Timing connects the two records. If fewer diverse candidates suddenly surface or more false positives advance, the team can locate the change and roll back to a known state.
Then give review a scheduled place in the process. The practical cadence is weekly false-reject reviews for the first eight weeks after any calibration change, monthly fairness metrics, and quarterly vendor and retraining reviews. Excluded candidates need attention as well as those recommended. Randomly sampling a small percentage of “not recommended” candidates into the hire pool, then measuring subsequent performance, provides a way to detect false negatives that would otherwise remain invisible.
How calibration governance keeps the hiring bar honest about what exceptional actually means for this team
A written standard gives the team a clear way to use interview feedback in calibration. When a hiring manager reports that a candidate looked strong on paper but could not do the work, the observation can be recorded and used to support a human-approved adjustment. The distinction is between evidence and imitation. Without it, repeated approval of candidates from brand-name employers or specific degree programs can pull the bar toward those credentials, whether or not they identify the strongest builders.
That is how credential creep becomes a strategic problem. The team may gradually narrow its search around familiar markers while believing it is refining its definition of ability. A written rationale makes the tradeoff discussable. If a new criterion demands a credential the market cannot supply at scale, a founder and TA partner can confront that constraint before spending months pursuing the wrong pool.
Candidates also respond to the standard they think they face. Researchers studying AI evaluation contexts found that candidates emphasized analytical traits and downplayed intuition and emotional traits, such as empathy, when they believed an algorithm was grading them. Creativity was a preliminary finding in that research. This adds another reason to question a narrowing profile, rather than assume it reflects the full range of available talent. A team that wants leaders who are inventive or good at building relationships needs a standard that can pick up those strengths.
Over time, the calibration log becomes institutional memory. A founder and TA partner can examine what changed, why it changed, and what followed instead of repeatedly reopening an undefined argument about what they want. Past decisions become available for correction as well as repetition. The advantage in hiring at speed comes less from having more AI than from applying an explicitly owned, continuously refined standard that can be tied to what successful hires actually look like.