How to Know If Your Definition of Exceptional Is Too Narrow Before You Open a Req
Test your hiring requirements against real market supply before you start recruiting.
Pre-sourcing calibration defines what exceptional looks like before hiring begins, then tests whether the talent market can supply it. The clearest warning that a hiring bar is too narrow is that too few people meet its essential requirements within the role’s pay and location constraints. A short calibration sprint, followed by a talent supply check, lets founders and talent leaders sharpen that standard before opening a req.
Why hiring managers write specs against candidates who don't exist in sufficient supply
A hiring manager starts with a clear picture of the person the team needs. They know the work, understand where the team is stretched, and can explain why each requirement belongs in the role. That confidence is a reasonable starting point. But knowing what would make someone ideal for the job is different from knowing whether enough people with that combination of experience are available. The first question concerns the work, while the second concerns the market.
The manager writes the requirements, talent acquisition turns them into a job description, and sourcing begins. Market feedback arrives only when the pipeline fails to fill, often weeks later. By then, the profile has become the standard against which candidates are rejected, even though its feasibility was never tested.
This gap in responsibility can occur even when people are competent. The hiring manager owns the standard, and TA owns the pipeline. Neither ownership automatically includes testing how domain, sector, seniority, tooling, compensation, and location interact before the search starts. Who is responsible for asking whether the whole combination exists in sufficient supply? Without an explicit answer, a team can mistake agreement about its needs for evidence that its search will succeed.
How requirements stack and compound to shrink the talent pool before you post the role
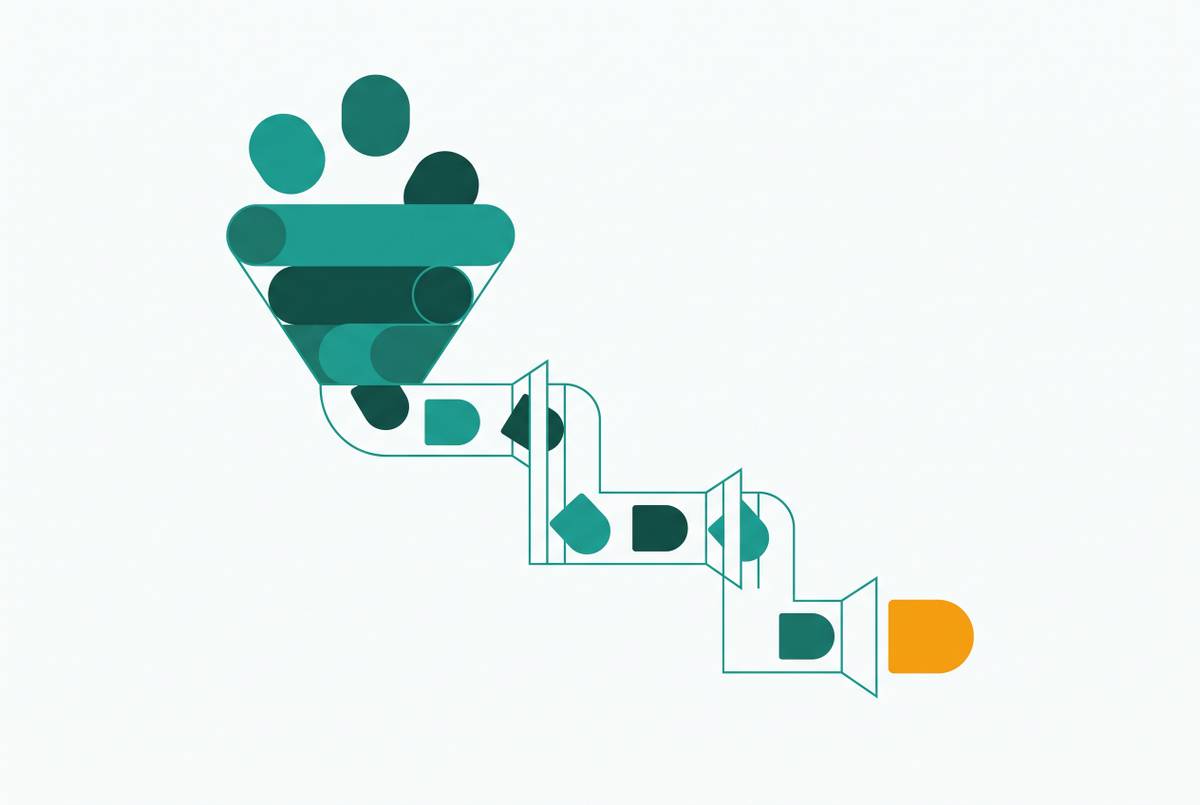
A candidate must meet the domain requirement and the sector requirement and the seniority requirement, while also fitting the tooling, pay, and location constraints. Each filter acts on the people left after the others have been applied. The pool therefore shrinks multiplicatively. A list can look reasonable item by item while describing a segment too small to support a search under normal time and compensation constraints.
The healthcare operations example shows how a surface requirement can hide a broader functional need. “Hospital-system experience” may stand in for “comfort with compliance-heavy, high-volume service operations.” Those are not the same test of capability. The first screens for a sector credential, while the second allows consideration of adjacent-industry experience in compliance-sensitive service operations. Reframing the requirement preserves the underlying need without assuming that only one employment history can satisfy it.
Whether that requirement is mandatory or preferred is itself a policy choice. It determines who gets considered. Yet when a spec does not distinguish between the two, every item can become a reason to screen someone out. Discovering it during the search means the team has already been looking within a pool narrower than the work required.
What "bar drift" actually is and why it happens in both directions
Even a reachable profile can become unstable once people begin evaluating candidates. Bar drift is the gradual movement of a team’s shared hiring standard without a deliberate decision to change it. It can move in either direction. The common cause is a reference point held in memory rather than an anchored, written standard tested against market evidence.
Upward drift happens when a team has not made an offer in a while and starts comparing each candidate with a remembered ideal. That ideal need not reflect anyone the market can supply. The team sees each new person’s gaps, but the candidate it imagines has none. The standard quietly inflates, adding an internal obstacle to the supply constraints already built into the spec.
Under pressure to fill the role, the reverse can happen. Interviewers judge candidates against the weaker people they have just seen instead of the original requirements, so someone can look strong mainly because of who came before. Score inflation, where “everyone's a strong yes”, and score compression, where “everyone's a 3”, are both bias signals after multiple hires in the same role family. Neither establishes that the panel has become better at judging talent. Both suggest that its anchor has weakened, making it harder to distinguish a genuinely scarce profile from an inconsistent evaluation process.
What a calibration sprint is and how it separates essential requirements from preferred ones
A calibration sprint is a timed role intake meeting, lasting under two hours, held before sourcing ramps. It brings together the hiring manager, TA lead, functional leader, and one or two consistent interviewers. Its purpose is to turn an ideal profile into a set of explicit hiring choices. Which abilities are indispensable, and which backgrounds are simply the most familiar ways of acquiring them?
The central question is “If we find someone exceptional in two of these three areas, which requirement can move?” It forces a trade-off into the open. A manager who cannot answer is implicitly asking for someone who satisfies every requirement simultaneously, without any compensation or flexibility in return. The question exposes whether the team can explain why each requirement deserves to remain essential.
Essential requirements are separated from preferences, criteria receive agreed weights, and interviewers share a definition of strong before meeting anyone. This makes evaluation less dependent on the early appeal of familiar credentials. Phenom's 2026 AI Recruiting Guide describes AI-powered matching and scoring for sourcing, as well as candidate ranking based on predefined screening criteria. But predefined does not mean well-founded. Calibration gives those criteria a defensible basis before a system applies them across the candidate pool.
How can you pressure-test job requirements against actual talent availability?
A calibrated spec is still a hypothesis until it meets the market. Internal agreement can establish what a team wants, but it cannot establish how many people could realistically do the job. That requires an external test. Talent market analysis examines where those people are concentrated, which employers employ them, how many competing searches seek the same profile, and what compensation range is competitive.
Talent intelligence platforms provide the market-feedback function that teams otherwise postpone until sourcing stalls. They use datasets to find passive candidates and help teams work out their hiring needs before a req opens. For a given role, they help teams check how many people meet the agreed requirements. A broad population of people with one relevant skill is not enough. Teams need to know how many satisfy the essential combination under the proposed search conditions.
To pressure-test that combination, a team should examine which individual requirements most compress the pool. Some may move to preferred if transferable experience can demonstrate the underlying capability. Others may need to stay essential, so changing pay or location may help more. The output should turn a description of the market into a decision about the search.
That distinction becomes especially important when scarcity is structural. Too few people have some skill combinations at any price, so offering more money cannot always make the original role work. The decision may instead be to scope the role differently. Conversely, where supply exists but the proposed parameters exclude it, compensation or location changes may meaningfully expand access. Market evidence separates a capability the work genuinely requires from a condition the employer has chosen, while there is still time to change that condition without losing weeks and pipeline credibility.
Why skills-based evaluation surfaces qualified candidates that credential-matching systematically misses
A wider spec achieves little if screening still rewards the old credentials. Candidates from adjacent industries may now qualify on paper, yet remain disadvantaged because their titles or former employers look unfamiliar. The bottleneck has only moved downstream. The team must change how it judges candidates along with the profile, so people in the wider pool get a fair assessment.
AI-assisted sourcing can identify transferable skills and adjacent-industry experience without an exact keyword match. That makes candidates visible whose fit would be missed by traditional title-and-brand searches. Visibility, however, is only the beginning. Teams must then check whether the assessment recognizes what they have actually built, shipped, or changed, and whether that evidence satisfies the sprint’s non-negotiable requirements.
AI assessment can also reproduce the very proxies calibration is meant to challenge. Tools trained on existing top performers can learn the demographic and credential patterns of that workforce rather than isolate the capabilities the job requires. Amazon's AI recruiting tool was trained on a decade of resumes drawn largely from men and learned to downgrade resumes referencing women's organizations or colleges. The ACLU describes reproducing workforce demographics as “virtually guaranteed” when tools are trained on current employee data.
Anchor evaluation criteria to evidence of work. Keeping that distinction clear lets a team weigh different paths to the same essential capability while holding to its standard.
Where human judgment remains essential and what happens when it's removed too early
Once data and tools handle more of the search process, the human role becomes more focused. AI can analyze calibration data, expand the pool, and score evidence of work. People still decide who is worth meeting. They also build the relationship through which a candidate understands the opportunity and decides whether to join.
The guide spells out this split, with AI doing repetitive tasks that take up time while humans make the calls at key steps. Drafting descriptions, finding candidates, personalizing outreach, scheduling interviews, and summarizing conversations can support that work. The hiring decision remains with a person. Whether someone will thrive in a particular team’s relationships and circumstances under pressure requires a human who understands both the culture and the moment.
A first interview conducted entirely by AI can be a reason to disengage, especially for someone with other options. The relationship is part of the assessment in both directions. A process that treats it as administration to eliminate can lose both useful signal and the candidate’s willingness to continue.
Every addition, removal, or reweighting should be visible, reasoned, and approved by a person. Making deliberate responses to market evidence distinguishable from unnoticed drift keeps people accountable for calibration after the first meeting ends.
The sequence founders and talent leaders should run before opening any req
For an early-stage team, a six-week failed search has a proportionally higher cost than it does for an enterprise. The practical response is to resolve the core hiring choices in sequence before opening the req. First, founders and talent leaders should write down what must be true on day one separately from what can be developed, trained, or demonstrated through transferable experience. The distinction must be explicit enough to guide screening.
Next, the team should run the calibration question about which requirement can move for an otherwise exceptional candidate. The team should agree on a trade-off in its answer. The supply check then tests the resulting essentials against the relevant market and competitive compensation. If the pool is too small, the team can choose a change to the profile, offer, location constraint, or role scope before committing sourcing effort.
Once those choices are made, the panel should spell out what strong performance looks like in terms it can observe. The final step is to agree on a recalibration trigger, using a signal such as pipeline conversion rate, scorecard score distribution, or time without an offer. That trigger gives the team a reason to revisit the standard before frustration starts changing it informally.
A small team needs a written standard, evidence that the market can supply it, and a clear point at which humans will reconsider it. Those are decisions to make before opening a req to avoid spending six weeks of hiring time learning them.