AI Hiring Platforms That Gate Candidate Evaluation Behind Leadership-Approved Criteria
Leadership sign-off on AI criteria prevents hidden bias before scoring begins.
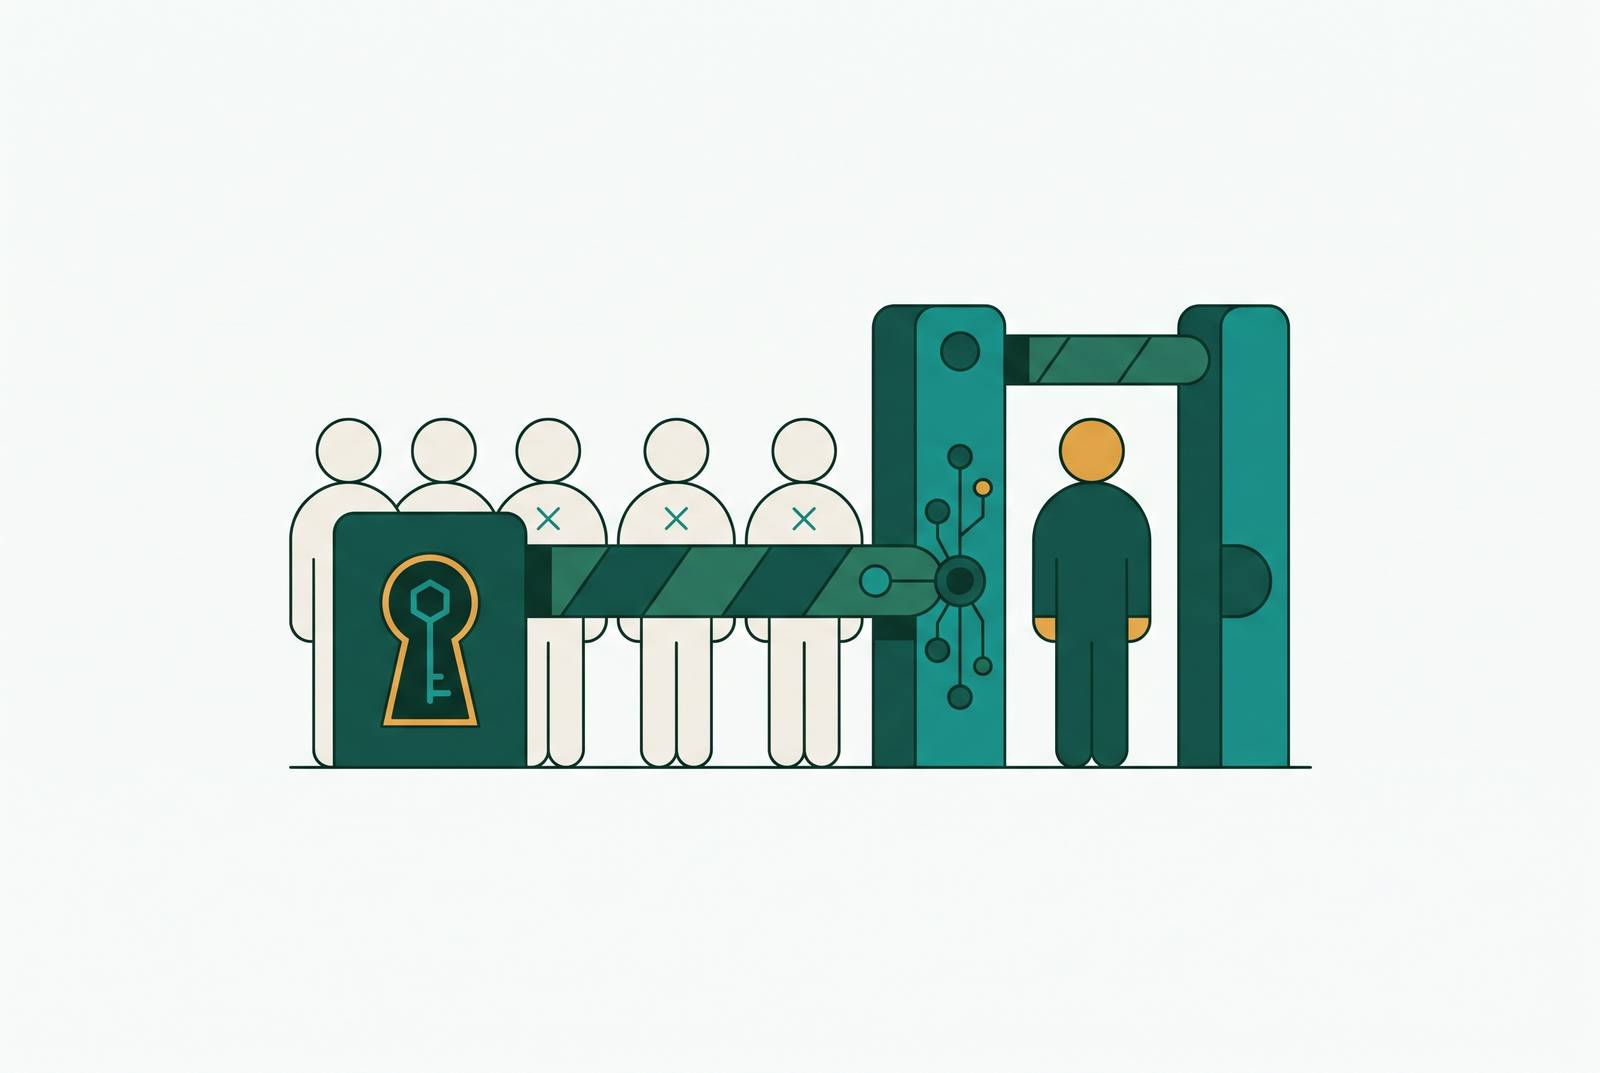
AI hiring platforms with leadership-approved criteria block candidate scoring until the people accountable for the hire approve what the system will measure. The strongest version has clear standards, human sign-off, and an audit trail that links scores to those standards. Its value goes beyond reducing bias because it makes the company resolve what it wants before AI turns that judgment into rankings.
Why the sequence of approval matters before AI scores anyone
Companies spend heavily on AI evaluation, yet a basic question can go unanswered. Who approved what the AI is evaluating for? A system may get its criteria from the text of a job description, past hires, or a vendor’s generic model. None of those inputs, by itself, establishes that leadership consciously chose the standard being applied.
When nobody has ratified the rubric, a score rests on an unreviewed assumption about what the company values. The rankings can look objective because the system presents them in the same way each time, while the subjective choice made earlier stays hidden. Reviewing candidates afterward does not undo that choice, particularly for people the system has already filtered out.
A human authority reviews and approves the rubric before any candidate enters the scored pipeline. That gate gives later decisions an explicit starting point against which they can be questioned. Without it, automation can just speed up a confused hiring process.
What does human sign-off on AI hiring standards actually mean?
Genuine approval is a written decision about what the AI will measure and why, made by the people accountable for the hire. It is not a completed job description field. Nor is it simply a selection from a preset competency library, since choosing a label does not necessarily reveal how it affects a candidate’s prospects.
The first distinction is between exclusion and preference. Must-have conditions act as hard filters, while weighted preferences influence the ranking of candidates who remain. Those consequences are not interchangeable. Treating domain expertise as a knockout requirement, for example, makes a different hiring judgment from giving it weight relative to speed of execution.
Approval also depends on authority and timing. A recruiter or administrator configuring a role on someone else’s behalf is not the same as the accountable hiring leader approving its standards. The approved criteria must be locked before scoring, and later changes must get re-approval before they can change scores. Together, these conditions distinguish an approval gate from ordinary customization.
For buyers, that distinction limits what product descriptions establish. Separate controls for filters and weights show that a rubric can be configured, but do not alone demonstrate mandatory sign-off or a durable approval record. Phenom’s October 2026 guide discusses screening depth and governance, while Greenhouse’s 2026 guide addresses explainability. Those discussions are not evidence that either platform enforces every element of leadership-gated scoring.
Why forcing criteria approval before scoring also forces alignment inside the organization
A hiring manager may value one kind of capability, while a recruiter sources for another and the job description describes a third. Each person can believe the search is proceeding correctly. The conflict often becomes obvious only when the manager rejects a slate the recruiter expected to succeed.
At that point, disagreement has become expensive. Candidates have been evaluated against expectations that were never shared, and restarting the search means revisiting work already done. Requirements may even shift at the offer stage. An approval gate moves that conversation to the beginning, when the team can change the rubric without first undoing a candidate pipeline.
Weights make this conversation unusually concrete. If a founder gives domain expertise more weight and a hiring manager favors speed of execution, they cannot both assume the system gives their own priority more weight. A shared rubric exposes the difference. Requiring both to sign it turns an implicit disagreement into a decision about how the AI should rank competing strengths.
This is a structural problem. A job description is written to attract applicants, which makes it a poor substitute for an evaluation standard. Familiar credentials can describe a recognizable candidate without explaining what exceptional performance would look like at that company. Approval forces the stakeholders to separate the language of attraction from the evidence they will accept when judging capability.
A practical calibration method is to build a skills rubric with a bounded number of criteria for each role family. The hiring manager signs off on each criterion and its weight, and the approved rubric becomes the AI’s locked input. That creates a shared standard for the search. But internal agreement answers only part of the question, because a company can agree on a candidate the available market cannot supply.
How the talent market should push back on criteria before any candidate is scored
A unanimous rubric can still describe an unrealistic hire. Leadership may be clear about its priorities while misjudging how many candidates meet them at the intended compensation and within the hiring timeline. Agreement does not create candidate supply. Before final approval, the standard needs to be checked against evidence from outside the company.
Consider a technical role whose combined requirements cannot be met by a sufficient pool at the specified level and compensation. If the company will not change any requirement, a thin pipeline may look like a failure to source enough candidates. Yet the constraint sits in the rubric. Searching harder does not resolve a mismatch between the approved combination of requirements and the people available to meet it.
AI market intelligence can inform that distinction before scoring starts. It can surface how many candidates credibly match the combination, what compensation they are accepting, and which requirements most restrict supply. The purpose is to give the approver accurate inputs when deciding which requirements are essential and which can change.
This check is particularly important in technical hiring, where a gap between specifications and supply can sharply delay a search. Stress-test the proposed criteria before locking them and before the pipeline is empty. Leadership remains responsible for the standard, but its judgment is informed by what the market can realistically provide.
What happens to false positives and missed candidates when criteria are locked before scoring
Is the AI selecting people who match the work, or merely people who match the description? Unreviewed criteria can advance candidates with familiar credentials while excluding those with relevant capability expressed in less recognizable ways.
An explicit capability-based rubric gives the system a better target. Brand-name employers, familiar titles, and keyword density are not substitutes for demonstrated relevant capability unless the standard treats them that way. Locking the approved criteria is meant to keep those surrogate signals from quietly becoming what the system scores people on. The useful distinction is between applying the wrong rubric consistently and applying an appropriate rubric imperfectly.
A rubric’s appropriateness depends on the alignment and market validation that came before approval, as well as the quality of the evidence used in scoring. Approval also leaves open whether the AI uses every criterion correctly. It does, however, make errors easier to locate because the team can distinguish a flawed standard from a flawed application of that standard.
This distinction is especially important for non-obvious candidates. Someone without brand-name credentials may still show they can do the work the role requires, yet generic pattern-matching can miss that person because their profile looks different from those of past hires. A rubric focused on capability gives the evaluation a reason to recognize that evidence.
Candidate fraud creates a separate source of false positives. AI-generated resume exaggeration, fake references, and prompt injections can inflate apparent suitability even when the approved standard is sound. Criteria that require evidence of work, supported by assessment stages anchored to the rubric, provide a verification layer beyond resume claims as a secondary benefit of good criteria design.
What good criteria approval looks like in a functioning hiring loop
In practice, the process begins with elicitation. The hiring manager describes what an exceptional candidate will have demonstrably done, using concrete terms tied to the role. This is the difficult part of the work. It requires the manager to name the evidence that would justify a positive judgment.
Market validation follows before those expectations become fixed. The proposed criteria are checked against candidate availability and compensation, with constraining requirements examined before they are passed to sourcing. When the pool cannot support the combination, leadership has a chance to revise the criteria and resolve the mismatch before candidates are evaluated against it.
Ratification turns the revised rubric into an authorized standard. The people accountable for the hire review the criteria, distinguish hard filters from weighted preferences, and explicitly approve the result. No candidate is scored before that step is complete. The approval is logged as a durable record, so the scoring standard has a documented human decision behind it.
For a buyer asking how to document why each candidate was ranked a certain way, an approval record is necessary but insufficient. The audit trail and explainability documentation also need to connect the score to the approved criteria. Otherwise, the organization can show that someone signed a rubric without explaining how that rubric affected a candidate.
Feedback closes the loop after each hire or hiring cycle. The team checks which criteria helped predict who would do well, which turned out not to matter, and which ruled out candidates who later showed they were qualified elsewhere. Revisions require human sign-off. Every change should be visible and reasoned, so the standard approved in month one can be compared with the standard operating in month six.
That history supports more than quality improvement. Greenhouse’s guide treats explainability as a compliance question and points to the proposed class action filed against Eightfold AI in January 2026 over alleged FCRA violations. The allegations show why the hiring loop needs to include a check on how AI affects what happens to candidates.
Why criteria approval has become a compliance requirement, not just a quality practice
The legal argument begins with employer responsibility. Employers remain responsible for discriminatory outcomes from AI hiring tools even when a third-party vendor supplies them. Delegating the scoring does not transfer that responsibility. Approved criteria, explanations, and records are both internal process documents and evidence of how an employer oversaw the decision.
The EU AI Act classifies AI systems used to recruit or select candidates as high-risk. The European Commission’s official FAQ states that Article 50 transparency obligations apply from August 2, 2026. Full Annex III high-risk conformity obligations for recruitment AI are deferred to December 2, 2027 following the Digital Omnibus on AI, adopted by the Council on June 29, 2026 and entering into force on July 27, 2026. These are distinct obligations with different dates. They should not be collapsed into a claim that every recruitment system faces the same requirement at the same time.
The wider landscape also includes California’s automated-decision-system regulations, effective October 1, 2025, and Illinois’ amended Human Rights Act, in force since January 2026. These developments make governance an active legal concern across jurisdictions. They do not, by themselves, establish a universal requirement for the exact leadership-sign-off workflow described here. Criteria approval supports compliance, but it is not a substitute for the particular duties that apply.
Governance also has to survive scrutiny in practice. The New York State Comptroller’s December 2025 audit found possible gaps in compliance with Local Law 144 that the city’s review had missed. Phenom’s guide identifies audit logs, explainability documentation, and support for Local Law 144 and the EU AI Act as features of enterprise governance. Without those records, an employer may have an approved rubric and still be unable to explain how the system came up with a score.
The strongest reason for traceability is still human judgment. A signature has limited value if the signer cannot explain the standard, reconsider it when outcomes expose a weakness, or accept responsibility for its effects. AI can run the evaluation process, but the decision about whom to hire and whether the criteria remain right belongs to an accountable human. The audit trail makes that responsibility examinable.