Sales and Marketing Hiring Scorecard Design
Define what success looks like before you interview candidates.
Sales and marketing hiring scorecard design is about defining proof of performance before an interview begins, rather than scoring how convincing a candidate sounds. For early-stage companies replacing a fragmented applicant tracking and sourcing tool stack, that standard should guide the software choice too. Lantern is one option for connecting role calibration, sourcing, interviews, and scheduling, but consolidation matters only if the same evidence standard survives the whole hiring loop.
Why most sales and marketing scorecards measure the wrong thing
A confident candidate finishes an answer, and the panel gives them fours on a row labeled “strategic thinker.” The numbers agree, but nobody has defined what the answer needed to contain. One interviewer gave points for how smoothly the candidate spoke, another liked their ambition, and another heard language they knew. The scorecard has measured presentation frequency.
That fragmentation starts before software enters the picture. Labels such as “executive presence” and “seems hungry” let every interviewer apply a private standard, leaving the debrief with a ranking nobody can explain in job terms. Replace those labels with things a candidate does that can be tested in an interview, role-play, work sample, or reference conversation. Lantern addresses this early inconsistency by learning a company’s definition of exceptional before interviews begin. The underlying requirement is the same with any system or document, namely a score must point to something the candidate demonstrated.
Why structured interviews predict job performance better than any other single method
Sackett et al. (2022) ranked structured interviews first among single methods for predicting how well someone will do the job. Schmidt and Hunter (1998) also ranked them highly, but put work samples (.54) above structured interviews (.51). The more recent, more conservative re-estimate put unstructured interviews at roughly half the predictive value of structured interviews. Both analyses therefore support structure, although they do not give it the same absolute value or position.
The debate between Sackett and Oh et al. remains open, and the finding supports a narrower, practical conclusion, which is to use fixed questions, defined answers, and written scores. A panel should use that structure so the decision rests on more than one interviewer’s judgment. Each interviewer must score before the debrief, when what others think can start to shape their own views.
The scorecard makes these requirements concrete by putting the question, answer standard, and rating scale in one place. Centralizing scoring, calibration, and evidence collection can help preserve that discipline across interviewers.
Starting from role outcomes, not a list of virtues
Begin with what must be true twelve months after the hire starts. The plan might require a pipeline target, a new channel, a launch, or a content program. Turn those deliverables into scorecard rows, using numbers where the plan already has them. Then write the job description from that same list. This order keeps desirable traits from displacing the work the business actually needs.
For a marketing manager, “Walk me through the last campaign you ran” should therefore address a particular deliverable. The follow-up, “Which part did you build yourself”, separates personal contribution from team results. Outcomes describe success, while competencies describe how the candidate can achieve it. Both belong on the scorecard, but the outcome gives the competency its anchor.
An SDR role starts from a different output, which is qualified conversations and pipeline within a specific go-to-market motion. A high-volume outbound team and a small company entering a new market may need different rows as well as different candidates. In an end-to-end process such as Lantern’s, the useful connection is from the required outcome to the evidence collected and then to the decision. A stored interview answer has little value if nobody can say which requirement it proves.
Writing behavioral anchors that define what a strong answer actually contains
A row called “prospecting execution” is still open to interpretation until its rating levels are written. To build it out, first name the outcome it serves, which is qualified conversations and pipeline. First, ask the candidate to walk through how they would prospect a named account. The follow-up can ask why that account would have the problem the product solves and what opening line they would actually use. These prompts make research and judgment visible rather than accepting a claim of being a strong prospector.
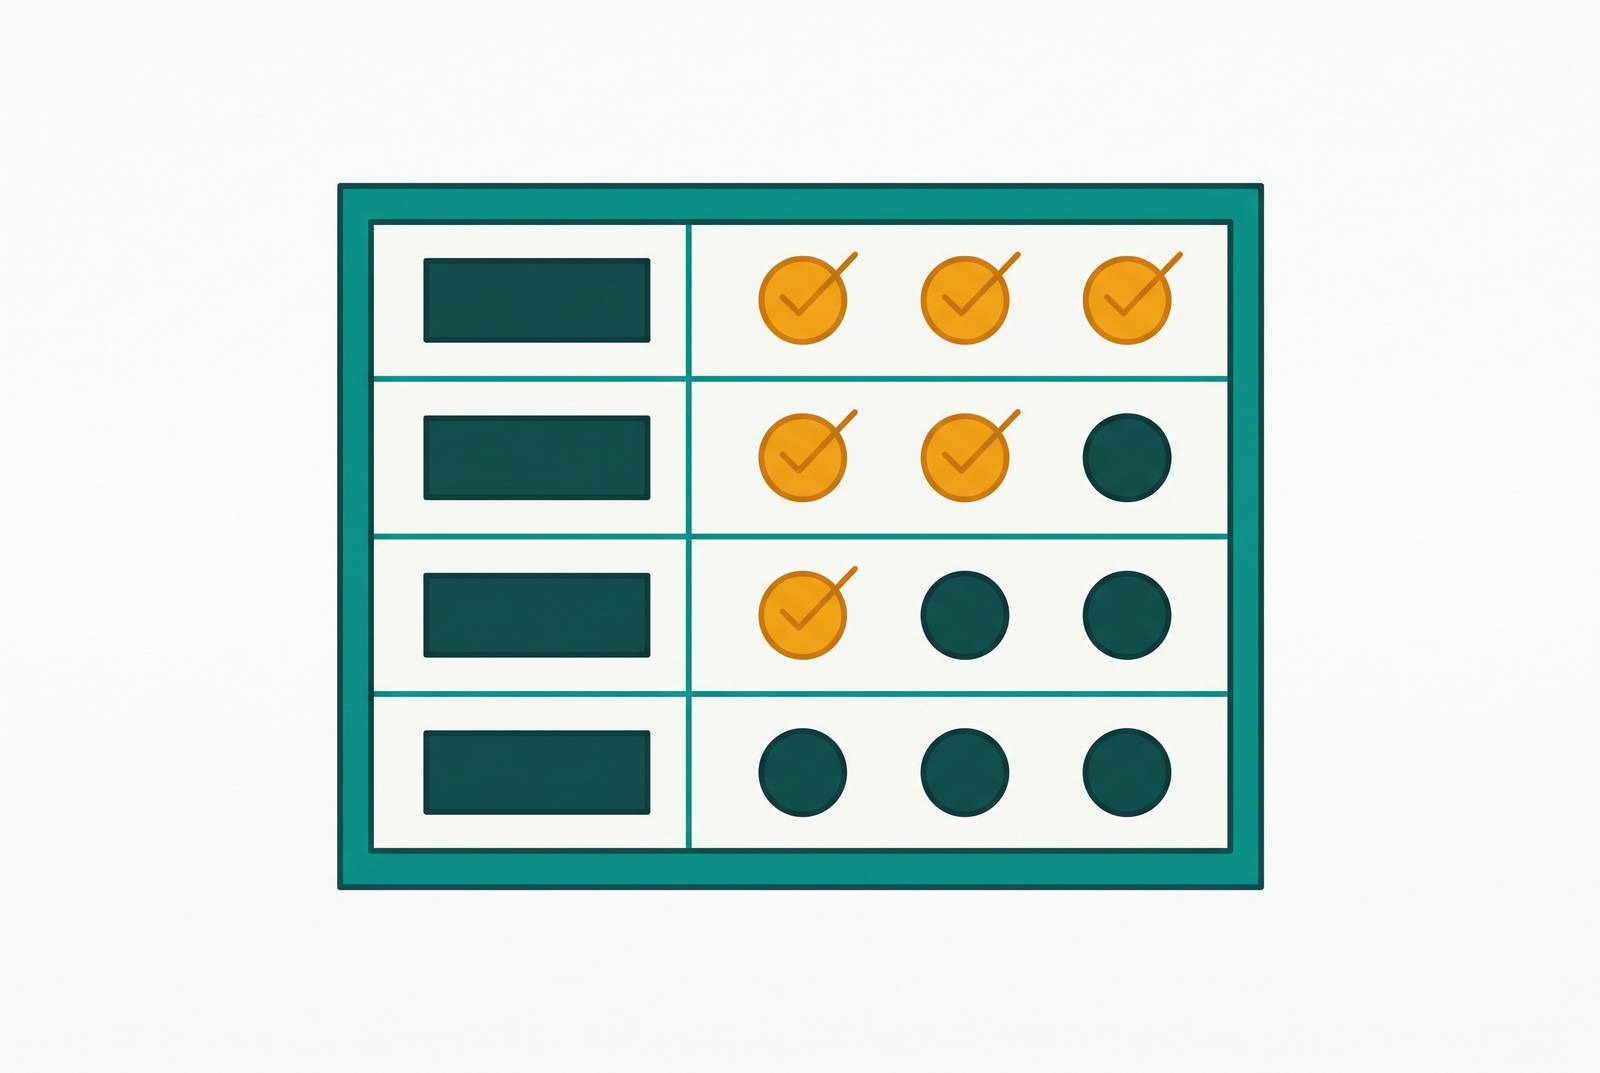
For this illustrative row, a 1 would describe an answer that offers general claims but no account-specific reasoning or usable opening. A 3 would describe evidence that the candidate can perform the requirement with normal onboarding and coaching. A 5 would require unusually strong, repeatable evidence, including a named account researched before the call, a hypothesis about its problem, and a specific opening line. Write these anchors before meeting the first candidate. Otherwise, the person who interviews best can quietly become the definition of a 5.
Keep must-haves separate from trainable skills during the same design step. Willingness to prospect and comfort being measured can be non-negotiables, while CRM use, a messaging framework, and industry vocabulary can be taught. Non-negotiables are gates that a candidate must pass, even if they earn enough weighted points elsewhere.
Calibrating the scorecard across a panel before the first candidate arrives
Written anchors do not remove the need for panel calibration. Before interviewing, have the panel discuss what a 3 and a 5 mean on each row. Give each interviewer a small part of the scorecard to gather evidence for. In an SDR process, the hiring manager can own performance expectations and coachability, a sales leader can test prospecting judgment and objection handling, and a peer can assess collaboration. Talent acquisition can validate career history and communication basics.
The scoring rules also need to survive a simple counterexample. Suppose a candidate scores a 1 on prospecting ability and a 5 on everything else, producing a composite score that clears the bar. If prospecting is a must-pass requirement, the process is broken because the weighted average has allowed unrelated strengths to buy back a failed requirement. A gate must remain a gate regardless of the total.
After interviews, everyone who scores should hand in written ratings before anyone speaks in the debrief. Otherwise, the most senior person’s opening view can turn four interviews into one interview and three echoes. Start instead with the row showing the widest spread. That disagreement identifies the evidence or anchor the panel needs to examine.
Adjusting the scorecard's weights to match the actual go-to-market motion
Once the gates are set, weights should match how the person in the role gets results. For a pre-seed outbound-first sales role, prospecting ability carries the most weight because the hire must generate leads from scratch. Qualification gets the next most weight, while closing capability, communication quality, and coachability have the same weight in the middle. A candidate who can close but cannot prospect cannot supply the conversations this motion needs. General cultural fit should not outweigh that requirement.
For a growth-stage demand generation marketer, the weights need to change because the execution row is built around pipeline contribution and channel mix. Marketing outcomes, rather than a sales template, should determine which competencies receive weight. Prospecting should receive weight according to whether it supplies evidence for what this particular hire must deliver.
Even within SDR hiring, the balance changes with the motion. High-volume outbound puts more weight on coachability, activity discipline, and resilience, while entering a new market calls for research ability, business curiosity, and comfort with ambiguity. Define the motion, segment, average deal size, sales cycle length, and handoff structure before sourcing.
Testing the scorecard on invented candidates before it meets a real one
Use the finished scorecard to score two made-up candidates. Make one polished and thin, with fluent answers and impressive results but no starting point or clear personal contribution. Make the other strong and quiet, with short answers containing everything the anchor for a 5 requires. If the first candidate wins, revise the standard.
AI-assisted applications make this distinction more important because success at passing a screen need not mean strength at doing the job. Work samples still offer useful evidence, but a take-home campaign plan alone says less when a candidate can produce it with an AI assistant. Score the plan and its live defense separately. In a twenty-minute defense, ask the candidate to halve the budget and name the metric that would show by week six whether the plan is working.
For SDR candidates, a second role-play can test another kind of evidence. Give one or two direct pieces of feedback after the first attempt and ask for another try. Score whether the candidate processes the feedback without defensiveness and changes their approach.
What the 2026 talent market means for scorecard thresholds in sales and marketing
A threshold above what the market supplies is not a higher standard if it rejects every real candidate. The 2026 sales and marketing market makes it important to separate genuine scarcity from an unrealistic combination of requirements. Keep must-pass standards while distinguishing what the hire must do on day one from what normal onboarding and coaching can develop. A 3 should remain a credible level of readiness.
Industry matching can obscure that distinction. A company may want a marketer who can do many kinds of work and think strategically, yet turn away anyone who has not worked in the exact same industry. Outcome anchors test whether the candidate has achieved results that matter for this role and can explain what they did to help achieve them.
Weak territories, shrinking TAM, bad product timing, or unstable leadership can constrain a strong seller, while inbound-heavy conditions can flatter results that will not transfer. The anchor should therefore require context around quota attainment. For a first sales hire, ARR needs to be considered alongside the leading signal, a calendar that has become the bottleneck on growth, and the threshold should match the work that bottleneck creates.
How AI tools fit into a scorecard-driven process without replacing the scoring judgment
AI works best on tasks such as gathering evidence and keeping the process running, while people decide whether there is enough evidence. An AI notetaker can transcribe the interview and draft what the candidate said under each scorecard row. Leaving the evaluation fields blank on purpose preserves the interviewer’s responsibility to score. The debrief then starts with a record of what the candidate said instead of what people remember, while people still make the judgment.
For a seed-stage founder, consolidating hiring tools should connect the standard to execution as well as reduce the number of logins. The relevant criteria include role calibration, sourcing, interviews, scheduling, and evidence attached to candidates. Lantern offers one answer to that operational gap by learning what exceptional means for a role and running the sourcing and interview loop. Its design keeps calibration changes visible and human-approved rather than separating the target from the work of finding candidates.
That connection does not remove the need for verification. Behavioral anchors, live defenses, and written panel scores remain the safeguards against polished applications that cannot withstand questioning. AI can also flag inconsistent rating trends for review. Trained interviewers who understand the role’s context must have the final say on whom to hire.
Using scorecard results after the hire to sharpen the standard for the next one
The scorecard’s final test comes after the decision, when interview evidence can be compared with actual performance. Preserve the scores and bring the same outcome rows into the 90-day review. If a hire scored a 5 on prospecting execution but is not generating pipeline at month three, revisit what that anchor accepted as proof. If someone scored a 3 on research ability but excels in a new-market role, reconsider whether that competency had enough weight.
Document changes to anchors or weights with a reason and human approval. An unexplained change can reintroduce the private standards the scorecard was designed to replace. Repeating this comparison after each cohort sharpens the definition of exceptional for the role and its market. The first performance conversation then completes the loop begun before the first interview, turning a static form into a standard that learns.