The Explainability Gap Between What Your ATS Promises and What an Auditor Actually Needs
Auditors need preserved records of criteria, versions, and reviewers, not just scores.
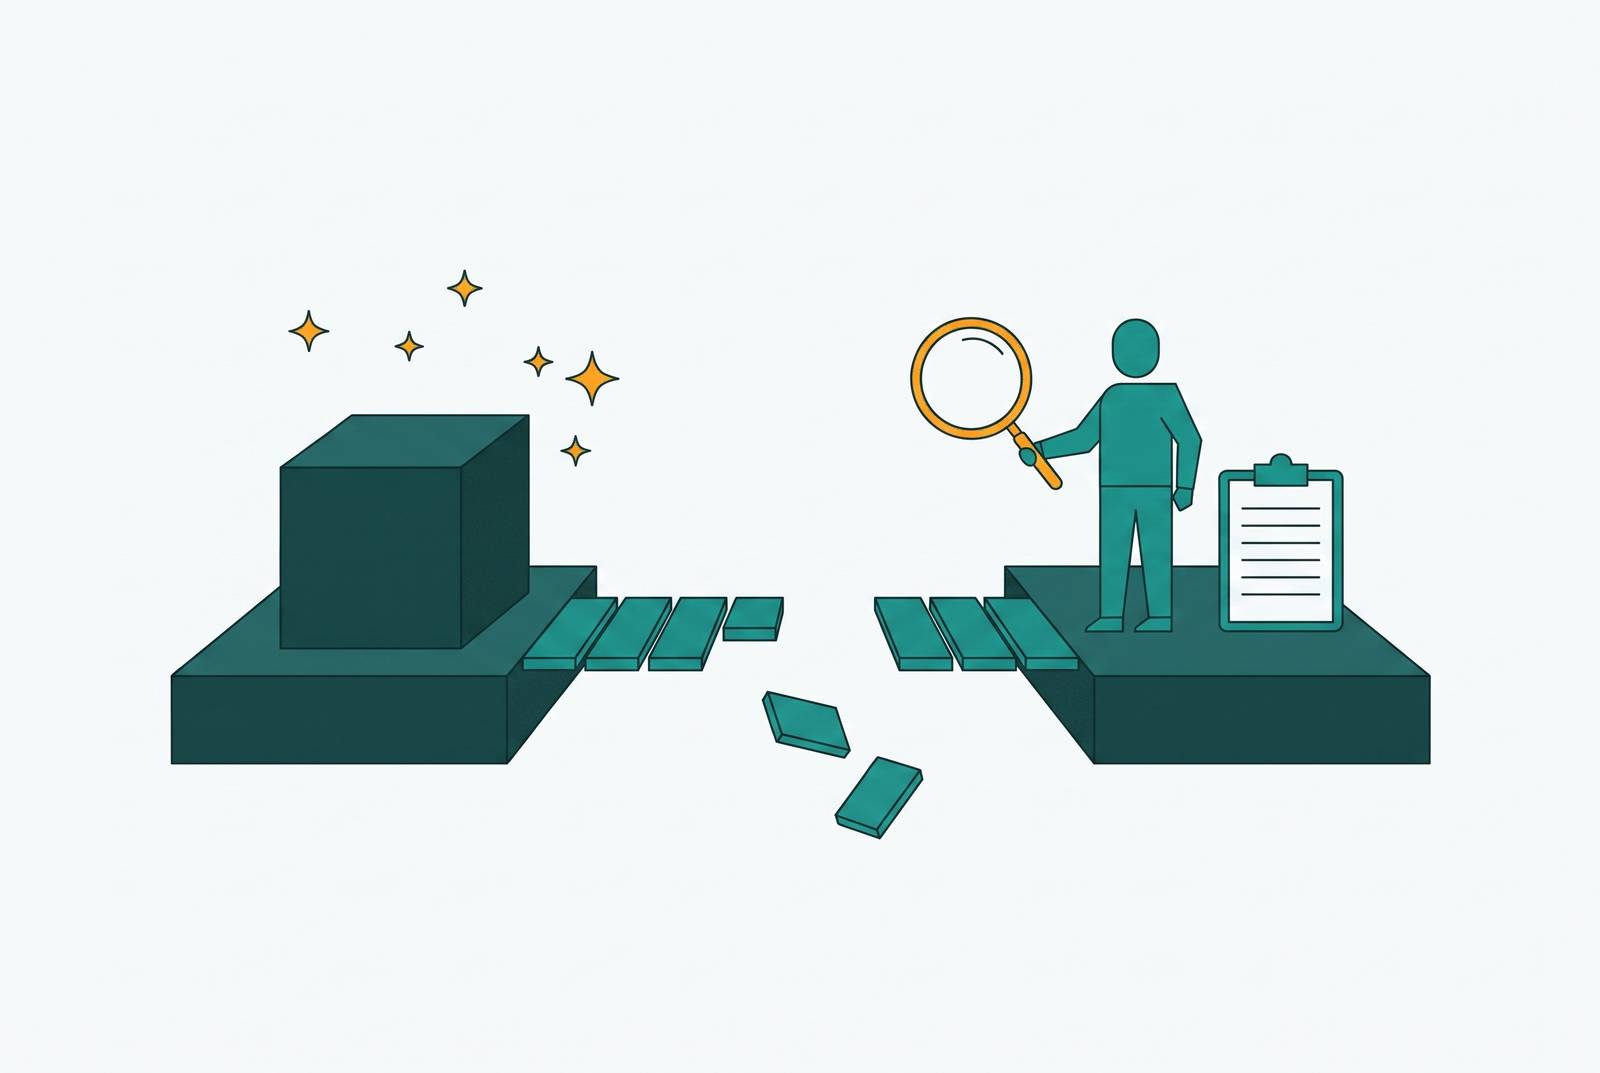
An AI recruiting tool with human-approved hiring standards and an audit trail needs more than explainable scores. It needs criteria approved before evaluation, evidence behind each candidate’s result, model-version records, and named human review before consequential decisions. An ATS promises to show a result, while an auditor needs a preserved record that makes it defensible.
Why ATS explainability and audit explainability are answering different questions
“Explainability” means different things to the people building hiring software and the people auditing its use. For a vendor, it often means that a recruiter can see a rank, a match score, or a skills tag and understand what to do next. For an auditor, it means being able to reconstruct who decided what, against which criteria, at which point in time, and with which version of the tool. Those are different questions about the same result.
The distinction is structural. Explanations help recruiters decide what to do next, while audit evidence lets people trace and challenge a decision. Why was this candidate ruled out? Answering that requires a link between the candidate’s evidence, the criteria agreed before the search, the system’s output, and the person responsible for the decision. More dashboard features cannot supply a history that was never recorded.
What the EU AI Act and overlapping US regimes actually demand from a hiring tool's audit trail
The EU AI Act explicitly names recruitment and selection in Annex III, including targeted job advertisements, analysing and filtering applications, and evaluating candidates, within its high-risk framework. Its reach extends beyond employers based in the EU to organizations whose systems are placed on the EU market or whose system outputs are used there. Location alone does not settle the question. The Act also distinguishes providers, who build the tools, from deployers, who use them. An employer therefore cannot discharge its own obligations by pointing to a vendor’s documentation.
The Act’s logging requirements concern records sufficient to identify risks, support post-market monitoring, and enable deployer oversight, with retention of at least six months. Article 12 sets out what must be logged, and Article 13 requires instructions on how deployers can collect and make sense of those logs. The distinction prevents a common overstatement of the law. The Act does not prescribe a closed list of recruitment log fields such as candidate scores and recommendations. The minimum fields it lists are only for remote biometric identification systems.
Human oversight also requires care in translation. The Act calls for oversight that lets people understand and monitor outputs, detect anomalies, and override the system meaningfully. That is more than clicking an approval button. But Article 14 does not itself require a human to review every rejection. A workflow that requires named review before each consequential decision is an operational standard for defensible oversight.
New York City’s bias audit law, Colorado’s SB 26-189, which repealed and replaced its prior AI Act, and the rules on notice and recordkeeping in California and Illinois can all apply to the same screening tool. Their definitions, deadlines, and documentation requirements differ, and Illinois’s specific recordkeeping details remain unfinalized following the withdrawal of proposed rules. Documentation is therefore central to demonstrating what was done. A workable standard for meeting these demands brings together subgroup performance data, ongoing monitoring, and two records an auditor can check directly: pre-committed criteria and a per-candidate decision log tied to a specific model version.
What most ATS platforms actually log and why that falls short
Most ATS explainability features expose outputs for recruiter action. A match score can tell someone who to review next without showing which model version produced it or which approved criteria were used to compare candidates. Action logs leave a similar blind spot. They often record who clicked or moved a candidate to another stage, rather than what the AI inferred, from which inputs, and with what weighting.
Model updates make that distinction harder to manage. When a vendor changes the scoring model, outputs produced before and after the change should not be treated as directly comparable without accounting for the version used. Most platforms do not version-stamp their outputs against the model state that produced them. The history can therefore look more consistent than it is. An auditor needs to know whether different results reflect different candidate evidence, changed hiring criteria, or a changed scoring tool.
If the team never recorded its legitimate hiring criteria, there is no fixed reference against which to test the model’s filtering. The first gap may precede the first score. A structured scorecard must set out the competencies, experience signals, and weights the team agreed on before screening starts.
Agentic pipelines spread this problem across more handoffs. When sourcing, screening, outreach, and scheduling run as a chain, the evidence for advancement or exclusion can be scattered across outputs that were not designed to form one decision record. Adecco’s Salesforce Agentforce deployment illustrates the scale, covering approximately 27,000 recruiters globally, with a first wave in the UK and expansion into France and other markets. Any system that works as a chain makes it hard to trace decisions when each stage keeps its own logs.
Semantic inference adds another layer of difficulty. It can be more accurate than keyword filtering, but its technical output is harder to translate into a hiring justification. A missing phrase is straightforward to trace. By contrast, a resume scored 0.63 against a job embedding does not, on its own, explain which approved requirement the candidate failed to meet.
Why post-hoc explainability tools do not close the audit gap
SHAP and LIME address part of this difficulty by estimating feature importance after a prediction. They do not reproduce the actual computation path the model followed, and different methods or baselines can yield different explanations for the same output. Their value is technical, but their reach is limited. An auditor asking why a candidate was excluded needs an explanation grounded in the team’s approved criteria. A candidate deciding whether to challenge the result needs a reason they can understand and contest.
HireVue’s 2025 Explainability Statement represents a serious attempt to document what a scoring model evaluates and how its competencies are defined. That is useful progress at the scoring layer. It does not establish which criteria an employer approved for a particular search or what a human decided after seeing a candidate’s output. The distinction between interview capture and AI scoring helps clarify the boundary. Capture supplies evidence for human judgment, while scoring asserts a result that needs its own criteria basis and candidate-level record.
Bias audits have a related boundary in time. A point-in-time audit cannot establish how a model behaves after an update or how an employer uses it outside its documented scope. An annual report leaves intervening behavior unaccounted for. The Act’s risk-management framework instead treats review and updating as an iterative process across the system’s lifecycle. Audit evidence must therefore be tied to the model version that was tested and backed by ongoing monitoring, because it cannot prove that a tool will stay fair forever.
What a defensible hiring decision record actually contains
A defensible record brings four components together, namely pre-committed criteria, per-candidate evidence, model versioning, and a human decision log. The criteria set the hiring bar before the first candidate is screened, including competencies, experience signals, and relative weights. They provide the reference point for testing consistency. They cannot be inferred afterward from the candidates the model favored, because past decisions may contain the very biases the audit is meant to detect.
OKQ8’s use of structured AI interviews through Hubert illustrates the criteria-first approach. Candidates are assessed against the same criteria, with the same answers receiving the same score tied to a documented response. That link makes the assessment inspectable. It lets a reviewer examine how a stated criterion was applied. Without that link, a shortlist may be orderly without being defensible.
Per-candidate evidence then connects the standard to the individual outcome. For every candidate passing through an AI-influenced stage, the record should show the inputs used, the output produced, and the human response. Pipeline averages cannot answer an individual challenge. Conversion rates and time-to-fill help a team analyse its process, but they cannot reconstruct a specific rejection. The output also needs its model version so that a mid-search update does not erase the distinction between different scoring conditions.
The human decision log establishes responsibility at the consequential step. Under this operational standard, a decision to advance, hold, or pass is attributed to a named person who reviewed the AI output before the decision was recorded. That can be done without a person reading every resume. It means designing the process so that review precedes the decision, rather than treating a later human action as proof that oversight occurred earlier. The log must distinguish a recommendation from the human judgment that followed it.
Sourcing needs the same care because a candidate can be ruled out before anyone sees their profile. If sourcing uses semantic inference to decide who enters the pool, the approved criteria must explain that boundary as well as later screening results. The audit trail begins before the shortlist. These four components therefore need to be in the decision record the employer keeps, as well as in the vendor’s general product documentation. Building that record requires both a governed workflow and software that can preserve its evidence.
How to close the gap: what hiring teams must build and what to require from vendors
For hiring teams, the first practical step is to make intake an approval point. Before opening a requisition, document competencies, evidence signals, and relative weights in a form that can be attached to the audit record. Timing is part of the evidence here. A criteria document created after screening is reconstruction. Assign a named reviewer at each consequential stage, including shortlisting, interview scoring, and final ranking, and record the review.
When a vendor updates its model, rerun a bias check before the new version processes live candidates, and version-stamp the outputs that follow. Run disaggregated subgroup analysis at each stage and cycle. Pass rates for the whole group can hide differences that are visible only in intersectional analysis. This makes monitoring responsive to changes in the tool rather than dependent on the date of the next annual audit.
Ask for the technical documentation covering system design, training data characteristics, known failure modes, and performance on representative populations. Ask for a bias audit tied to the current model version that includes disaggregated subgroup results. Version identity is essential to that request. Also check whether the vendor gives advance notice of updates, version-stamps outputs, and updates the documentation before the new version goes into live use.
The vendor’s instructions should explain intended scope, performance limits, known failure modes, and the human oversight measures referred to in Article 14, including technical measures that help deployers interpret outputs. These documents support employer oversight without replacing it. A bias report, model card, and change log offer a different basis for scrutiny from a promise that the tool is fair. During procurement, assess whether the employer can use those materials to understand and govern its own deployment.
The right agentic architecture shares one approved hiring context across sourcing, screening, interviews, and analytics. Agents bring forward evidence and recommendations, and named humans record the final decisions they make based on those outputs. Integration with an existing ATS, such as Greenhouse, Lever, Ashby, or Workday, keeps the audit record with the transaction record. Governance remains a continuing team responsibility. Signing a data processing agreement with a compliant vendor does not close the gap unless the employer maintains the intake, oversight, and monitoring disciplines that make each decision traceable.